The mysterious and undeciphered Voynich manuscript has caused consternation among code-breakers, linguists and scholars of medieval literature for more than a century. But now experts think they’ve worked out why it’s so hard to crack: It was bound incorrectly in the 15th century, meaning the pages are out of order. The new linguistic analysis of the document has moved researchers closer to figuring out what the text was all about.
The Voynich manuscript is a medieval codex made up of leaves of parchment carbon-dated to the early 15th century. Its 240 pages are covered with about 38,000 words of a unique script called “Voynichese” along with illustrations of people, plants and astrological symbols. Also known as the Beinecke Cipher manuscript, the document was initially owned by a Holy Roman emperor and was purchased by Wilhelm Voynich in 1912. Since 1969, the manuscript has been in the collection of Yale University’s rare book library. Experts have unsuccessfully tried to decipher the manuscript for more than a century.
“We don’t know if it’s a code,” Lisa Fagin Davis, study co-author and executive director of the Medieval Academy of America, told Live Science. “But there are some odd characteristics of the Voynich manuscript in terms of its physical structure.”
Latest Videos FromLive Science
When doing research on the number of scribes who copied the document, Davis realized from the handwriting that the manuscript’s pages alternate in ways that don’t make sense. In addition, she said, “there are several examples where the image goes off the page in the middle and comes out on the other side, even though there are a bunch of pages in between.”
In a study published Monday (Oct. 19) in the journal Digital Medievalist, Davis and co-author Colin Layfield, an information systems researcher at the University of Malta, suggested that the inconsistent structure of the enigmatic manuscript is the result of someone mis-binding a manuscript they were unable to read.
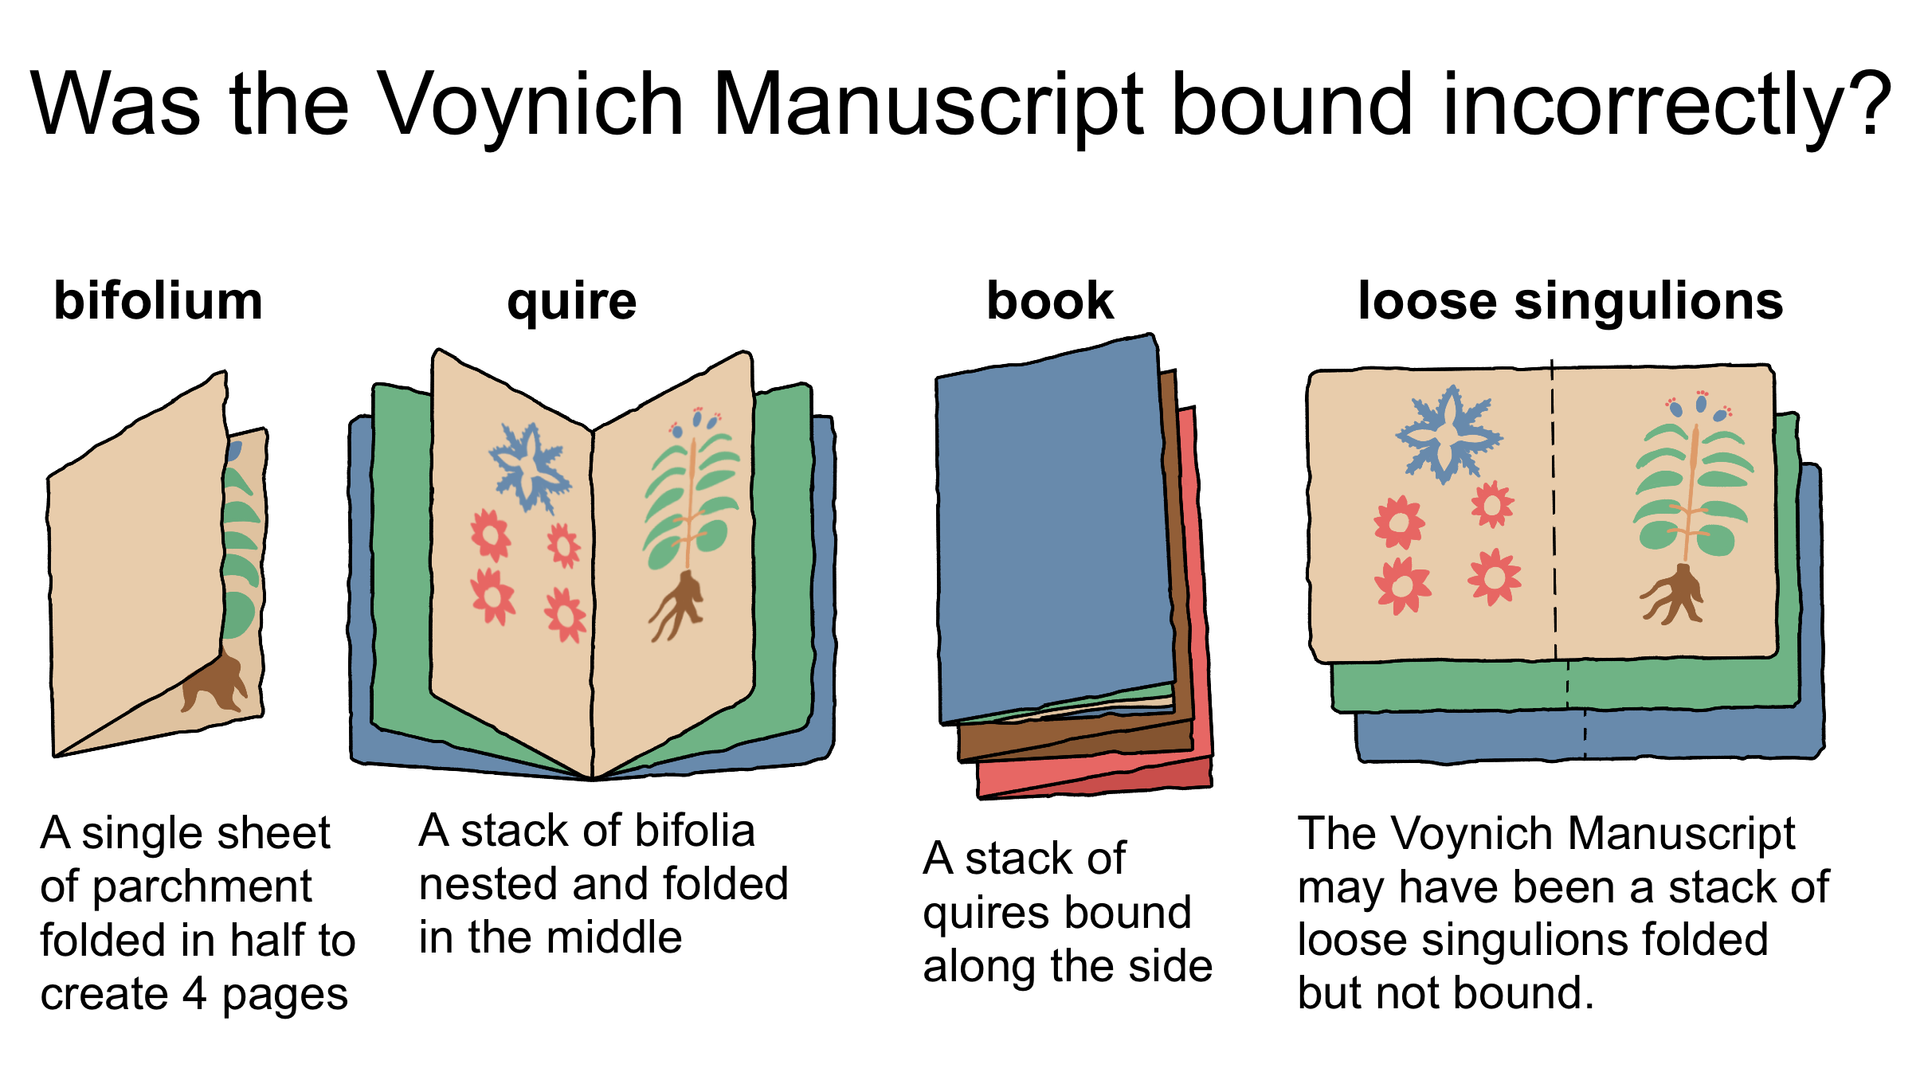
An illustration of how the Voynich manuscript may have been bound incorrectly.
(Image credit: Quinn Reynolds for Live Science)
Medieval manuscripts were made up of rectangular sheets of parchment (animal skin), typically folded in half to produce what experts call a bifolium. Around five bifolia would typically be nested together, creating what experts call a quire. Then, a stack of quires would be bound together along the spine to create a book. However, Davis and Layfield suggested that the Voynich manuscript was intended to be a stack of singulions — a series of loose bifolia never meant to be bound together as a quire or a book.
This is not the first time a researcher has suggested the Voynich manuscript has pages out of order. But Davis and Layfield analyzed the graphic properties of the untranslated document to see if their hypothesis made sense.
Get the world’s most fascinating discoveries delivered straight to your inbox.
“We’re viewing it as a text and assuming it has a message,” Layfield told Live Science, which means it should be possible to statistically compare blocks of text to see if they’re similar or disconnected. Layfield used a technique called latent semantic analysis (LSA), which is a natural language processing technique invented in the 1980s to find hidden patterns in texts.
LSA is particularly useful for small sets of data, Layfield explained. “Modern AI techniques need ridiculous amounts of data to train on, which we just don’t have. We’ve got just 35,000 or so words. That’s it.” The researchers’ LSA analysis of the Voynich manuscript revealed that some pages had low similarity, suggesting they may not have gone together, while others had high similarity, bolstering the idea that they were supposed to be read together.
By looking at the Voynich manuscript as a collection of singulions, Davis and Layfield solved some of the nagging issues with the document.
“When you start to think about it in the context of the other strange features of the manuscript, all of those problems are resolved,” Davis said. “It solves the problem of each scribe writing one sheet. It solves the problem of the images crossing the gutter.”
This means that any previous work on the Voynich manuscript that assumes it was ordered correctly now needs to be reconsidered, she said, but it also means there is new progress on the book.
“This work helps us think about whether there’s actual meaning underneath it all,” Davis said. “It doesn’t get us there,” she said about a definitive translation, “but it moves the ball because you can’t make sense out of a book where all the pages are mixed up.”
Davis is optimistic that someone will crack the Voynich mystery, in part because a similar modern puzzle known as Cain’s Jawbone has been successfully deciphered by a handful of people. This devilishly difficult linguistic puzzle from the 1930s consists of 100 pages of a murder mystery arranged in the wrong order. Due to the unique nature of the text and its vague, stylized language, even AI has failed to solve it.
“We have some ideas for other work we want to do,” Davis said. For example, there’s a large water stain in the upper margin of some of the pages of the Voynich manuscript. “The stain should be symmetrical from one page to the next but it’s not. That also supports the idea that the manuscript is bound out of order.”
Davis and Layfield are thinking about ways to compare the stain shapes across the pages, as that may help them reorder the incorrectly organized pages.
for informational purposes only. We do not claim ownership, accuracy, or liability for the content provided. All rights belong to the original publisher.
Contains information related to marketing campaigns of the user. These are shared with Google AdWords / Google Ads when the Google Ads and Google Analytics accounts are linked together.
90 days
__utma
ID used to identify users and sessions
2 years after last activity
__utmt
Used to monitor number of Google Analytics server requests
10 minutes
__utmb
Used to distinguish new sessions and visits. This cookie is set when the GA.js javascript library is loaded and there is no existing __utmb cookie. The cookie is updated every time data is sent to the Google Analytics server.
30 minutes after last activity
__utmc
Used only with old Urchin versions of Google Analytics and not with GA.js. Was used to distinguish between new sessions and visits at the end of a session.
End of session (browser)
__utmz
Contains information about the traffic source or campaign that directed user to the website. The cookie is set when the GA.js javascript is loaded and updated when data is sent to the Google Anaytics server
6 months after last activity
__utmv
Contains custom information set by the web developer via the _setCustomVar method in Google Analytics. This cookie is updated every time new data is sent to the Google Analytics server.
2 years after last activity
__utmx
Used to determine whether a user is included in an A / B or Multivariate test.
18 months
_ga
ID used to identify users
2 years
_gali
Used by Google Analytics to determine which links on a page are being clicked
30 seconds
_ga_
ID used to identify users
2 years
_gid
ID used to identify users for 24 hours after last activity
24 hours
_gat
Used to monitor number of Google Analytics server requests when using Google Tag Manager